01LLM evaluation · Agent designLUUK AI · Sep–Oct 2026
Testing an LLM agent that never answers the same way twice
A 310-test answer-quality suite on frozen production data, then a rewrite of the agent that the suite could prove.
9–13% → 0.2–0.5%
empty answers
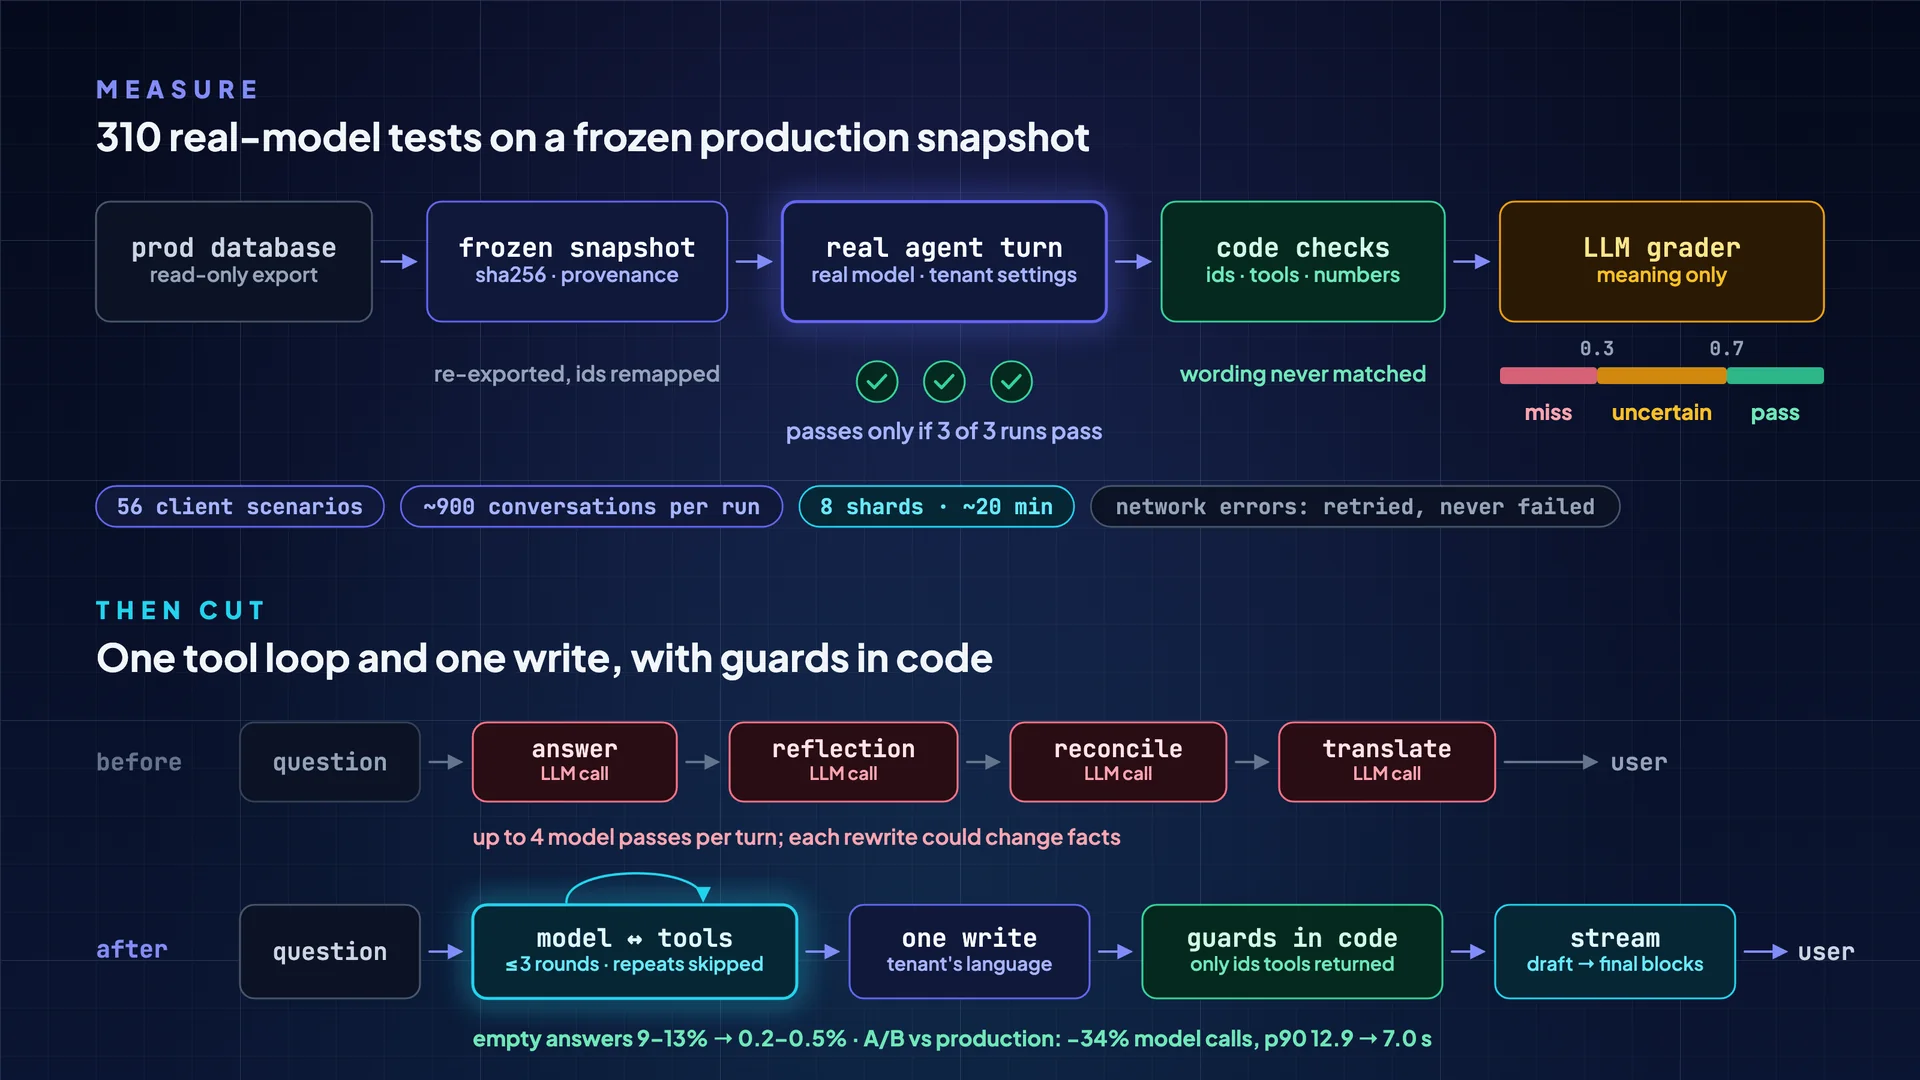 Open the diagram full size
The problem
Our sales assistants answer shoppers and brokers by calling tools over a live catalogue and knowledge base. After the first answer, up to three more LLM passes rewrote it (reflection, reconcile, translate), and each could change facts. Nobody could say whether a change made answers better or worse: the old tests checked helper functions on an old data dump and stayed green while the agent was broken.
Why it was hard
- The same question gets a different answer on every run, and models differ in how they use tools.
- Code can't judge meaning, and an LLM judge is noisy too.
- The test must run the agent exactly as deployed, on data that doesn't drift, while production data drifts and every re-sync changes ids.
- A full run is about 900 real conversations, so it costs real tokens, and network errors must not count as failures.
What I did
- 1Froze production data: read-only exports with a sha256 and provenance for every file. A refresh maps pinned ids to their new ids.
- 2The harness runs the real turn on the real model with the tenant's own settings, and I checked that it matched production. At first it didn't: a different token budget, search threshold and dictionary.
- 3Code checks come first (ids, tools and numbers precomputed from the snapshot); an LLM grader judges meaning only, with an "uncertain" band. A test passes only if all 3 runs pass, wording is never matched, and network errors are retried, never failed. About 20 minutes on 8 shards.
- 4Then rewrote the turn: a tool loop and one write, guards in code (it can only recommend ids the tools returned), the round budget stated in the prompt, and no fallback that hides an empty answer. An A/B against production proved it before the merge.
Results
310
real-model tests across 56 client scenarios, 3 of 3 runs to pass
9–13% → 0.2–0.5%
turns ending in an empty answer
−34%
model calls vs production in an A/B, 6 questions × 3 runs (embedding calls −82%)
12.9 → 7.0 s
p90 latency in the same A/B